Introduction
My portfolio gets very different readers. A recruiter clicking through from a LinkedIn job post wants to know whether I am hireable. A developer arriving from a GitHub repo wants architecture and code. A static page serves both of them the same thing, which makes it a printed brochure. So I built a page that rewrites itself for whoever is reading it, and the most useful thing it taught me had nothing to do with web design.
Evolve treats every slot on the page as a gene: each audience keeps its own population of page genomes, Thompson sampling chooses one per visit, and every 30 minutes losers retire and winners breed. Deciding who is visiting is the job of OpenJev, a free typed-decision API I host on top of Laya, an open-source small model for structured decisions. The interesting part was not the bandit or the genetics. It was what happens when that classifier is wrong.
When personalisation makes things worse
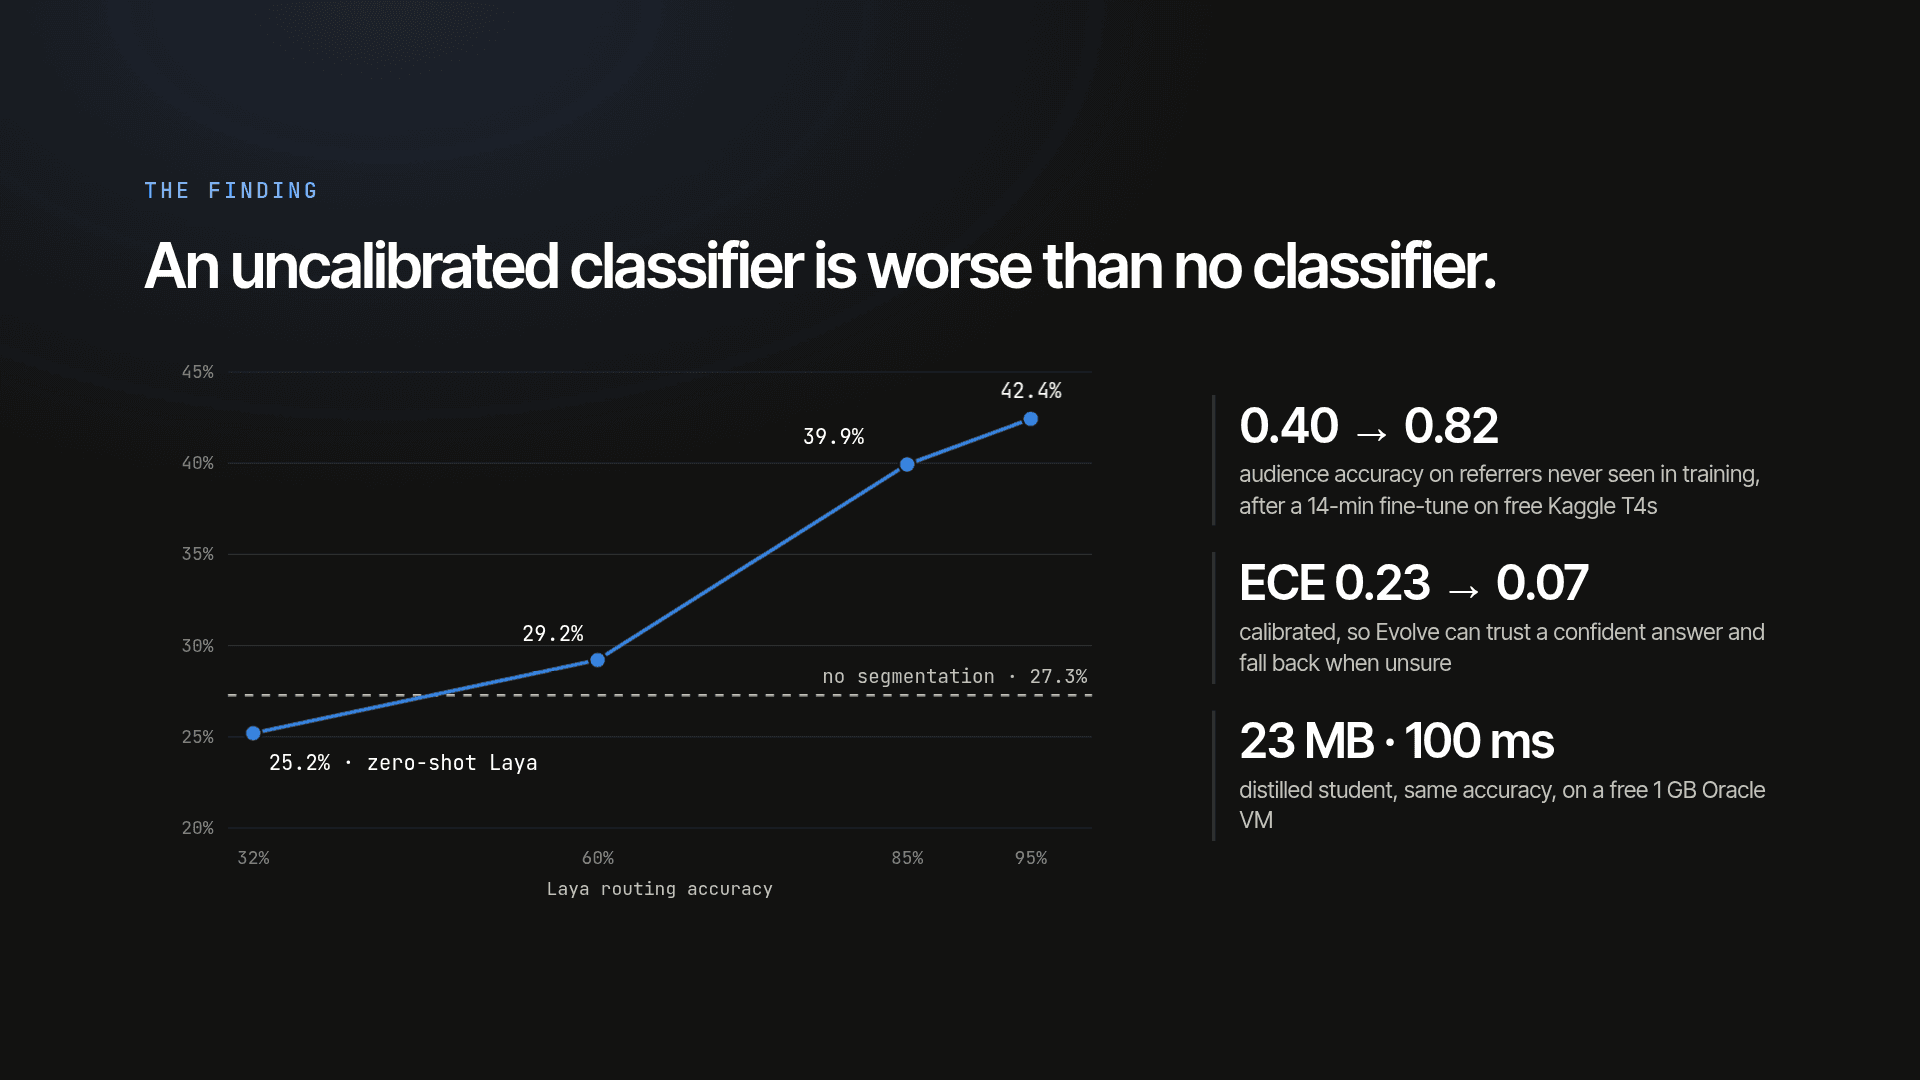
Before training anything I wrote a simulator: twenty worlds of five thousand visits where each audience secretly prefers different genes. Segmenting by audience lifted conversion from 18.8% with classic A/B testing to 39.9%. Then I swept the classifier's quality. Zero-shot Laya, which scored 0.32 on my hand-written evaluation and labelled every live visitor a developer, dropped conversion to 25.2%, below the 27.3% you get with no segmentation at all. A confidently wrong classifier splits traffic into populations that each learn from the wrong people.
Calibration is what lets a system be wrong safely. If the model says 'recruiter, 0.52', the page can fall back to the global population, but only if 0.52 really means 0.52.
Architecture
I did not hand-label thousands of visits. I wrote a seeded generative model of portfolio visitors: sample a hidden audience and intent, then sample everything the edge can observe from it, such as the referrer host, campaign parameters, landing page, language and device. Because the model is known, every row's target is the exact Bayes posterior rather than a hard label. Six thousand rows and fourteen minutes on Kaggle's free GPUs took audience accuracy on twelve referrer hosts never seen in training from 0.40 to 0.82, and calibration error from 0.23 to 0.07.
The fine-tuned model needed 1.6 GB of RAM and 1.4 seconds per decision on my laptop, and a laptop is not a server. So I distilled it into a 23 MB MiniLM student with one calibrated head per question, exported it to int8 ONNX and moved it to Oracle's free 1 GB VM. It matches the teacher (0.823 against 0.817 on unseen referrers) at about 100 ms per decision. A D1 cache answers repeat visitors in 11 ms, and every call runs after the response, so visitors never wait on the model.
What I prioritized
What made it hold together on ₹0 of infrastructure:
- Exact Bayes targets. Synthetic visits labelled with true posteriors teach the model to be uncertain when the evidence is weak.
- Abstains when unsure. The fine-tuned model abstained on 3 of 7 genuinely ambiguous visitors and on none of 53 clear ones.
- Distilled for free hosting. A 23 MB int8 student keeps the teacher's accuracy on a 1 GB VM at about 100 ms per decision.
- Holdout by design. 10% of visitors always see the original page, so the real lift can be measured honestly.