Introduction
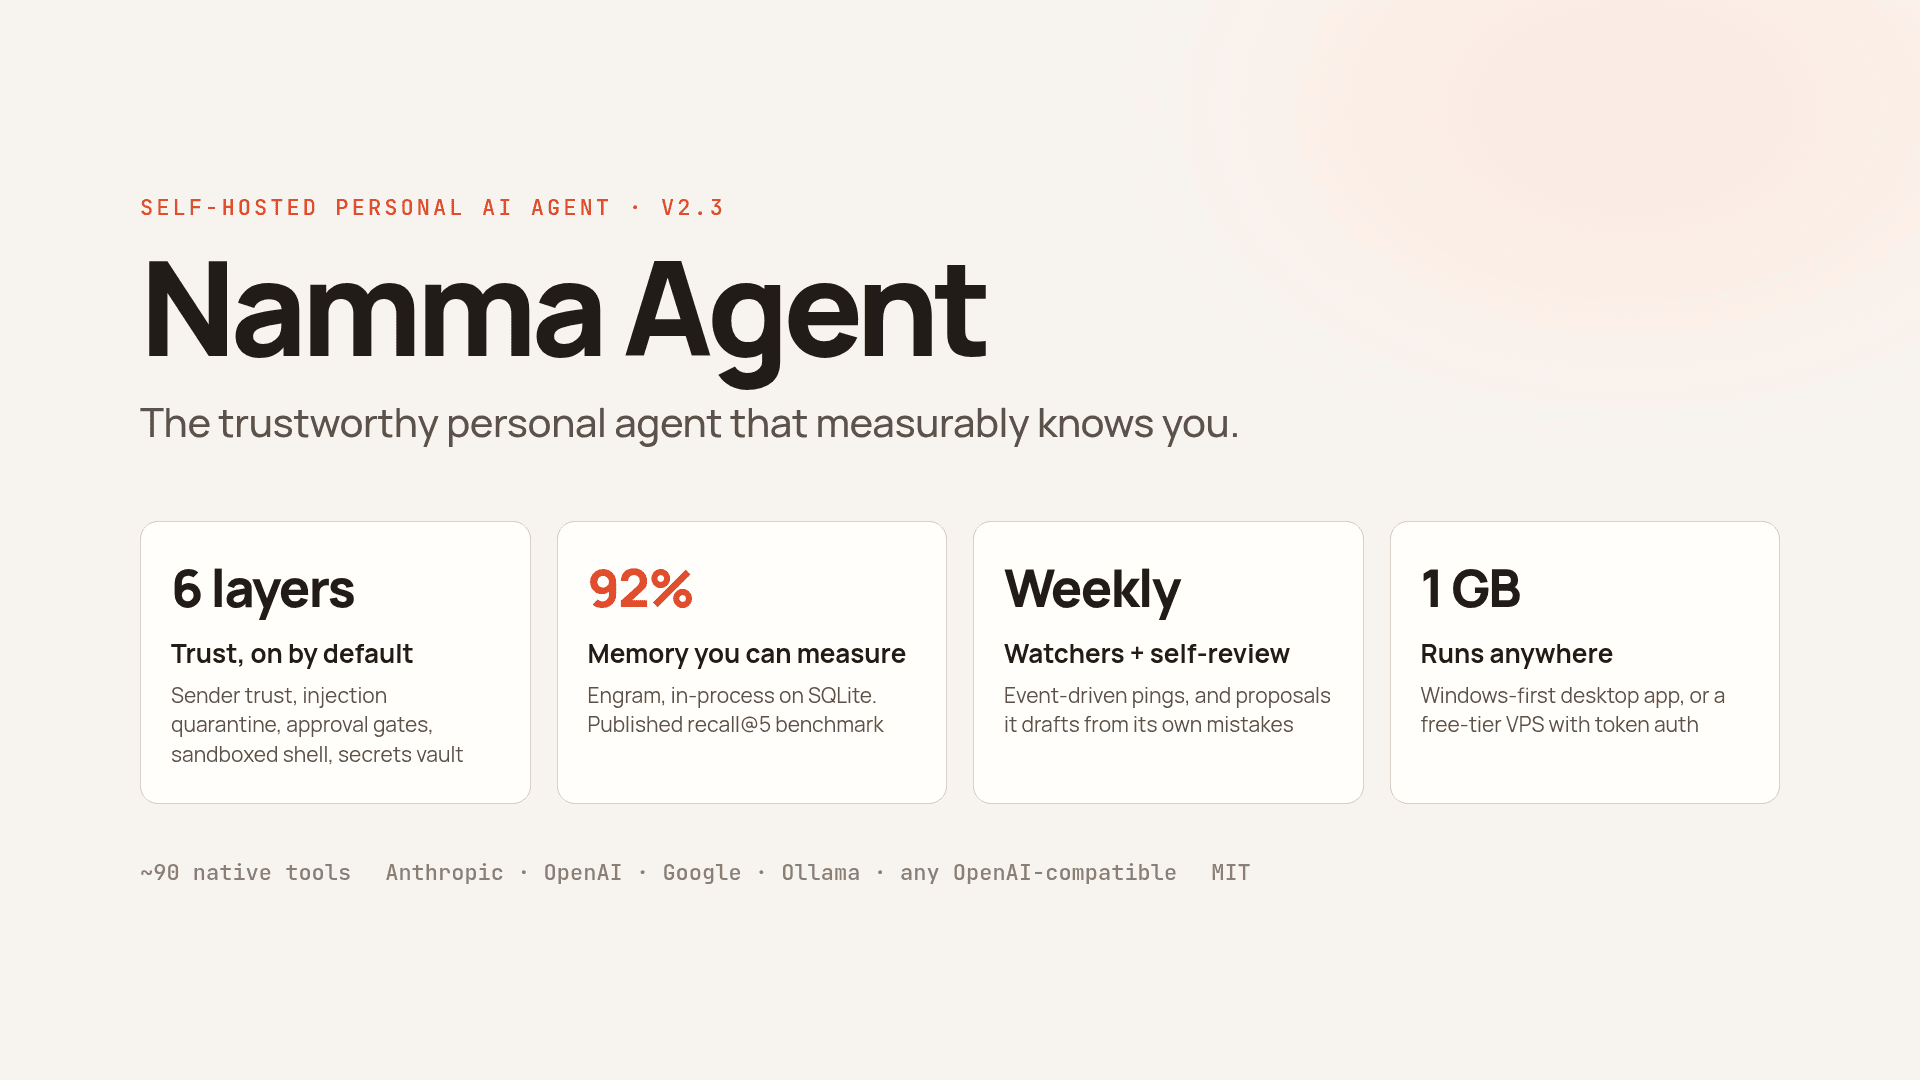
In June I wrote about giving Namma Agent a living knowledge graph by plugging Cognee in over MCP. It demoed beautifully. Three weeks later I removed it as the agent's memory. This is the story of why, and of the memory engine that replaced it: one that lives in a single SQLite file, never puts a model in the recall path, and publishes a number for how well it remembers.
The graph was never the problem; operating it was. Every recall went from the agent over MCP into a Docker container and through an extraction pipeline, so the agent capped recall at twelve seconds and still saw timeouts, while writing a memory needed a fifteen-minute budget. The graph only grew when auto-ingest was on, and then it filled with raw messages. Even the user's name needed a tool call. Memory has to be boring and always on, and this was neither.
What a personal memory actually needs
When I wrote down what failed, the list was not about semantic search. The agent needed to know who it was talking to without a lookup, to keep only facts worth keeping, to notice when a new fact replaces an old one, to understand the machine it runs on, and to get better while idle. Most of all, 'it remembers you' needed to become something I could measure rather than something I demoed.
'It remembers you' is a claim. A recall number with a weekly trend line is a fact.
Architecture
Engram is native and in-process: one SQLite file, no container, no cold start. It has six layers. Core memory about the user and the agent is bounded, versioned and injected into every prompt, so 'who am I?' costs zero lookups. Episodic memory keeps sessions and summaries. Semantic memory stores facts with validity windows alongside an entity graph of nodes and relations. Procedural memory holds skills, and environment memory models the host machine, including drives, folders and WSL paths, which fixed a long-running file-path bug.
Writes happen in a background worker. A cheap salience gate drops commands and short messages, one model call extracts facts, and a second resolves each one against similar facts as add, update, delete or no-op, so a changed preference invalidates the old one instead of contradicting it. Reads use no model at all: BM25, the entity graph, episodes and optional vectors are fused with reciprocal-rank fusion, filtered to facts that are valid now, and injected as data. A sleep-time consolidator summarises sessions, merges duplicates, decays stale facts and writes insights.
What I prioritized
What changed when memory became a measured engine instead of a service:
- Zero-lookup identity. Bounded core memory rides in every prompt, so the agent never has to query a container to know who you are.
- Facts that change. Add, update, delete and no-op resolution with validity windows keeps memory consistent over time.
- No LLM in recall. Fused BM25, graph and episodic search stays in-process and fast enough to run on every turn.
- A number, not a promise. A reproducible recall@5 benchmark, re-run weekly by the self-review, tracks memory quality as a trend.