Introduction
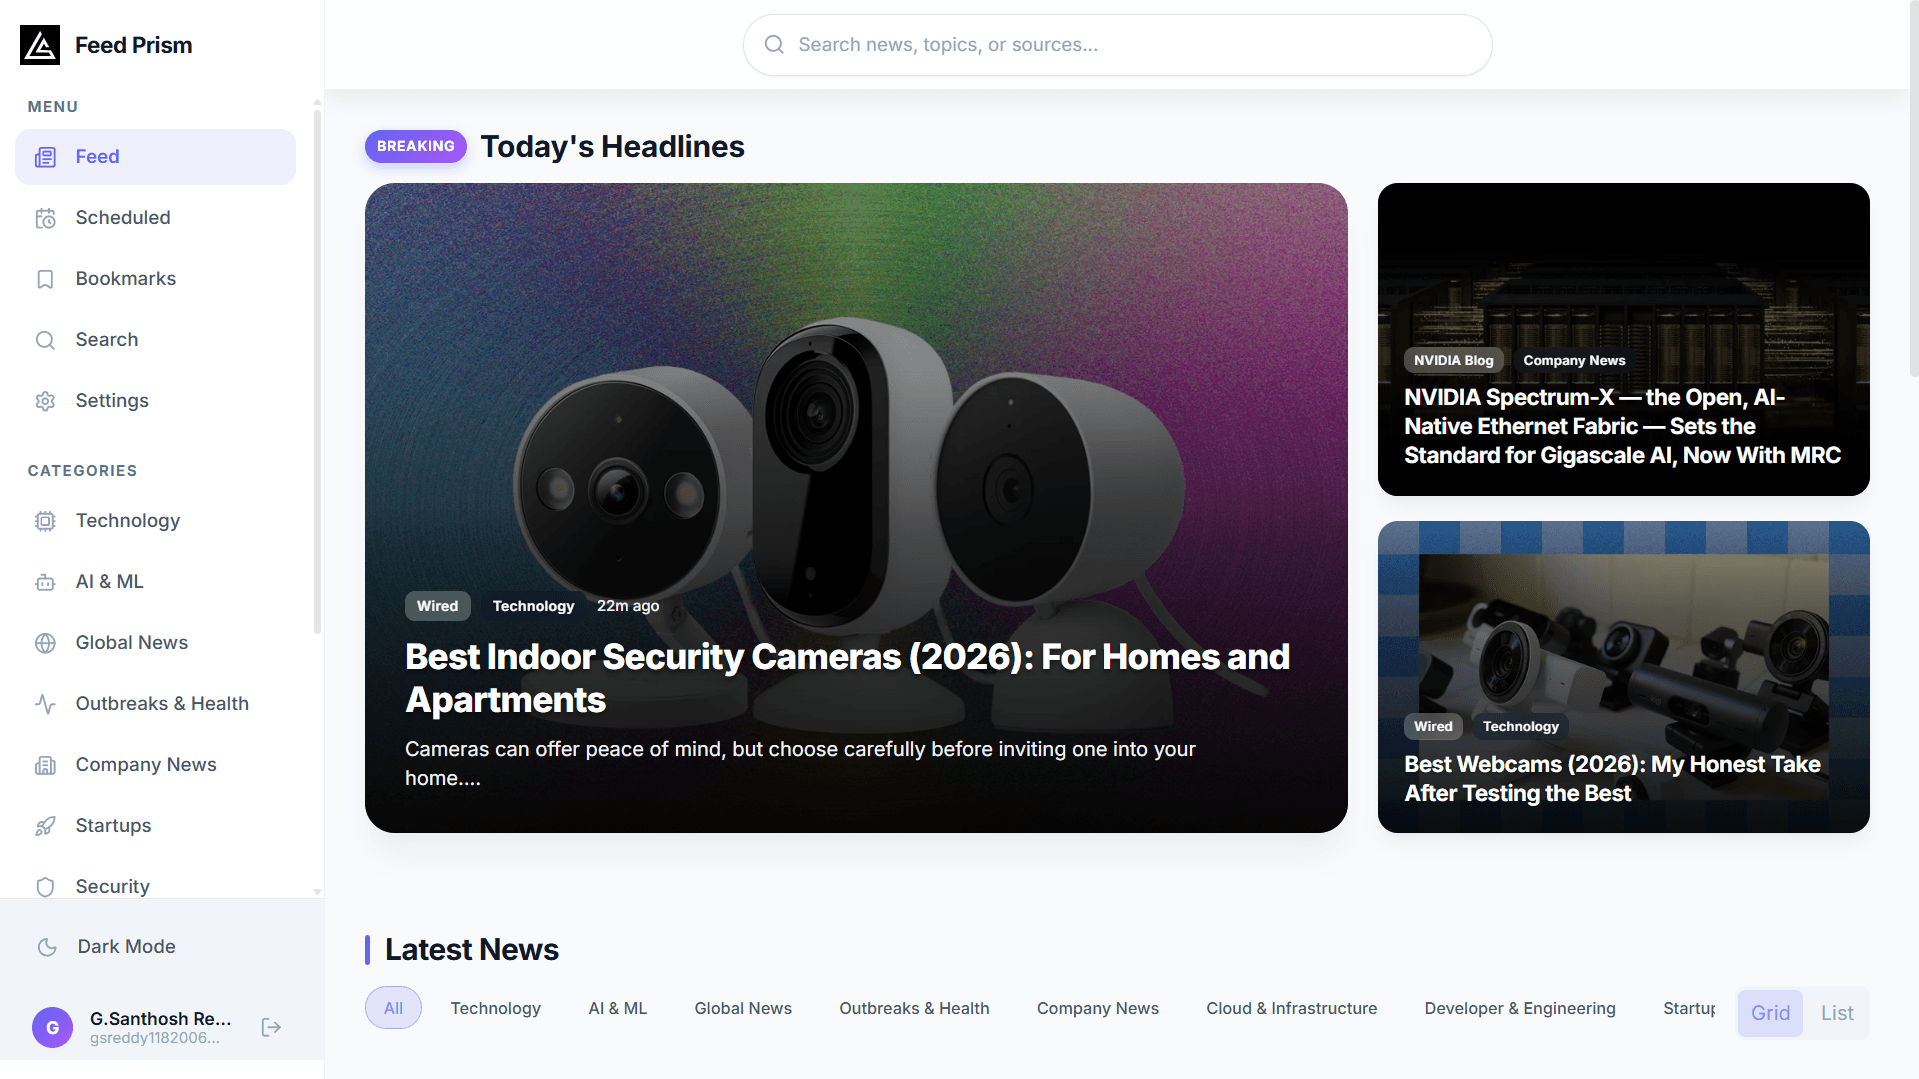
Feed Prism started as a question: what would a news aggregator look like if it actively monitored and categorized intelligence from over 500 global sources in real time? The product is a powerful, intelligent news command center featuring an automated event-driven ingestion pipeline, smart cryptographic deduplication, and a high-fidelity dashboard for tracking tech giants, startups, and global events.
The problem with static aggregators
Existing news readers act as dumb pipes, overwhelming users with a flood of duplicated content and unstructured noise. They cannot intelligently filter articles across hundreds of feeds, do not inherently normalize disparate XML data formats, and offer no granular intelligence monitoring for specific sectors like global health or cybersecurity. For a knowledge worker, that is the inverse of useful.
A news platform should ingest, normalize, and deduplicate information autonomously before it ever reaches the screen. Anything less is just an endless, uncurated inbox.

Architecture
I engineered a highly resilient, event-driven ingestion architecture powered by Supabase pg_cron that triggers automated fetch cycles every three minutes. To bypass serverless execution timeouts, the pipeline implements an algorithmic Batch Selector that processes sources in rotating groups of ten, ensuring feeds are continuously refreshed without choking the network.
The data layer ensures zero duplication through a two-layer cryptographic mechanism: every incoming article URL is converted into a deterministic SHA-256 hash, which is then evaluated against a PostgreSQL unique constraint using a batch UPSERT with ON CONFLICT DO NOTHING. The resulting data is indexed using native tsvector columns for sub-millisecond full-text search.
What I prioritized
A few of the technical decisions that mattered most:
- Algorithmic Deduplication. Utilizing SHA-256 URL hashing and PostgreSQL upserts to process batches of articles in a single database query, reducing execution time from 40 seconds to 3-5 seconds.
- Batched Ingestion. A rotational pipeline state machine that processes feeds in discrete waves to guarantee reliable execution within strict serverless time boundaries.
- XSS Prevention & Normalization. Autonomous HTML sanitization and cross-format normalization (RSS 2.0, Atom, RDF) applied strictly at the ingestion layer.
- Full-Text Search. Native integration of PostgreSQL tsvector and pg_trgm extensions for high-throughput indexed search capabilities.