Introduction
The modern internet is a massive, overlapping echo chamber. When a major tech company makes an announcement, 500 different RSS feeds and news outlets broadcast the exact same link within seconds. If you are building a real-time intelligence aggregator, how do you prevent your database from filling up with 499 identical copies of the exact same event?
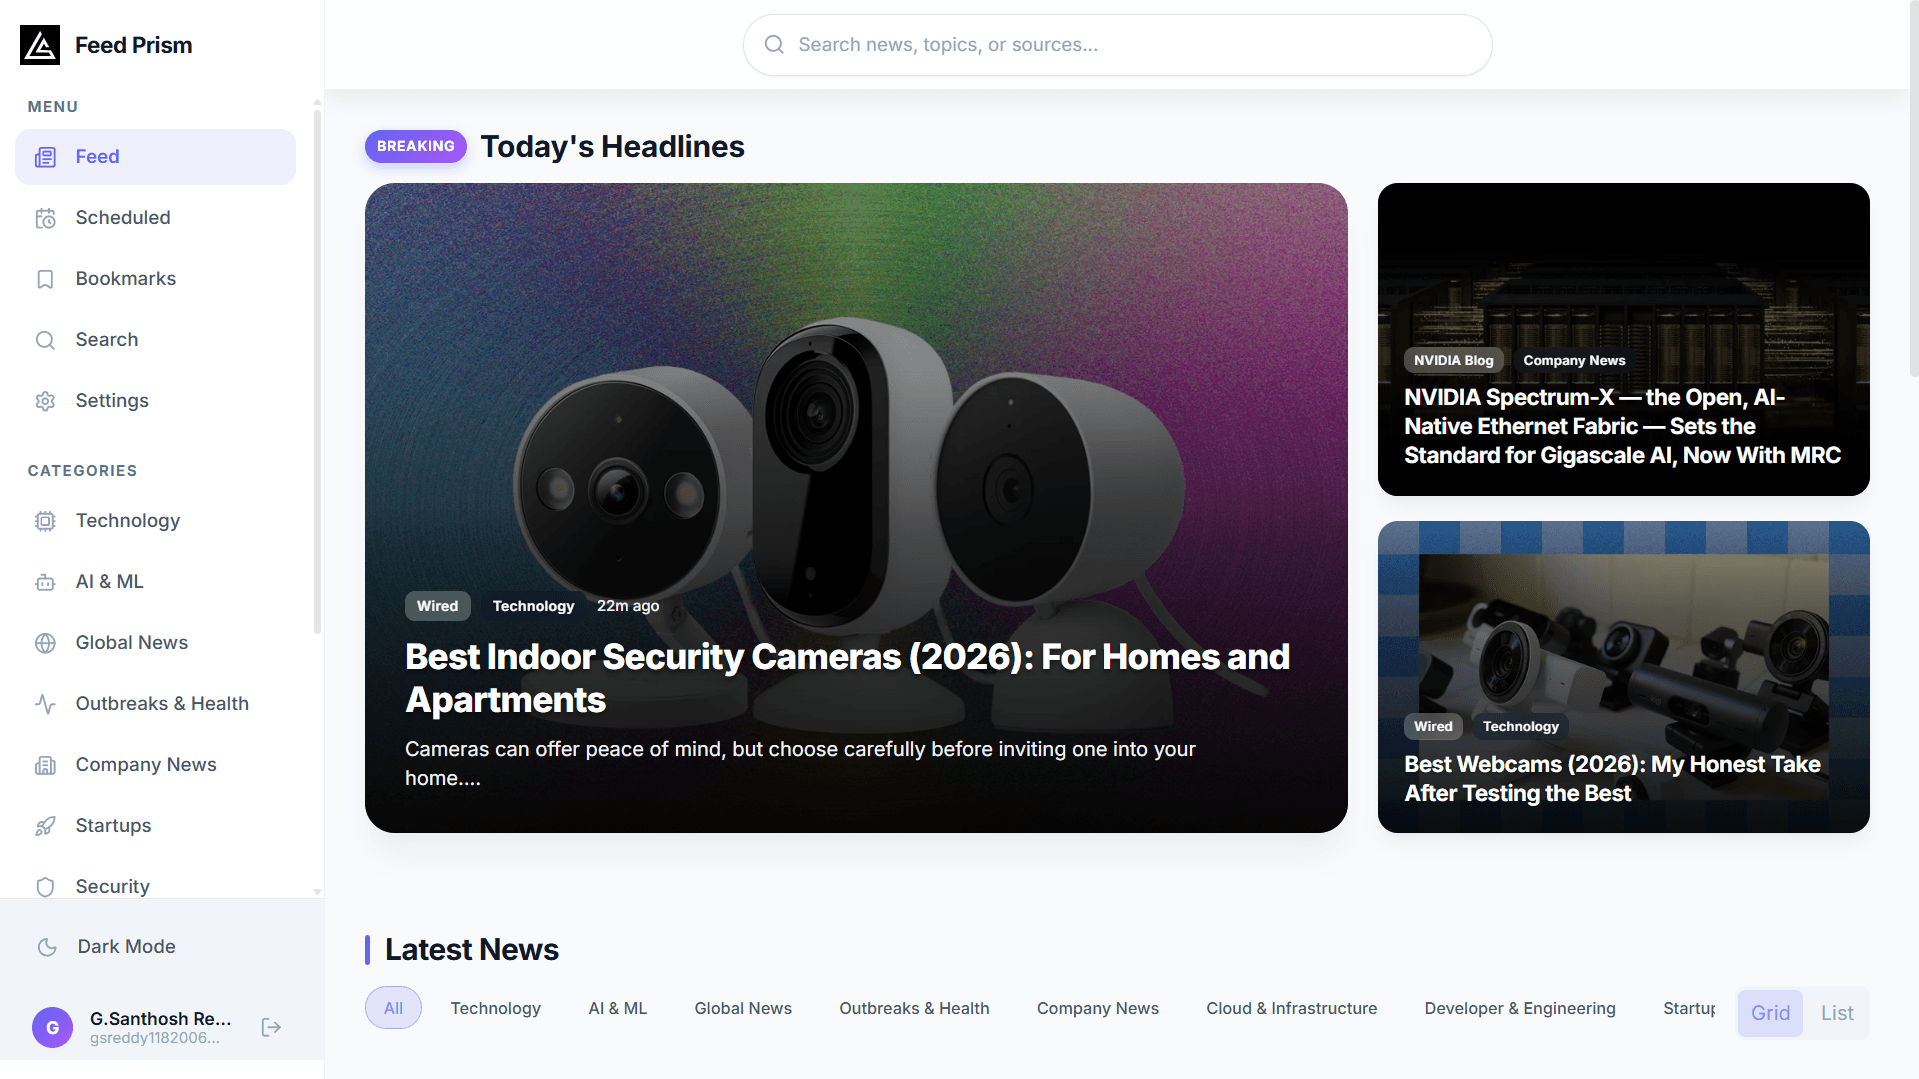
Feed Prism is an autonomous news command center that ingests data from hundreds of global sources. Very early in the engineering phase, I encountered the 'Avalanche Problem'. When the `pg_cron` pipeline triggered a fetch cycle, thousands of unparsed XML items would flood the edge functions simultaneously.
The High Cost of Application-Layer Filtering
The naive approach to deduplication is to fetch all articles, query the database to see if the title or URL already exists, and if not, insert them. This is an N+1 query nightmare. If you fetch 1,000 articles, you make 1,000 read queries, followed by a potential 1,000 write queries. In a serverless environment with strict execution timeouts, this approach crashes the system instantly.
You cannot deduplicate data in application memory when dealing with massive throughput. You must push the logic down to the bare metal of the database engine.

Architecture
We implemented a deterministic Cryptographic Deduplication layer. Before an article ever touches the database, the Edge Function normalizes the URL (stripping tracking parameters, UTM codes, and trailing slashes). It then runs this pure URL string through a SHA-256 cryptographic hashing function. This yields a deterministic, 64-character hexadecimal string. We set this hash as the PRIMARY KEY constraint on the PostgreSQL `articles` table.
Instead of doing read-checks, the pipeline blindly fires a massive, single-batch `UPSERT` (Insert or Update) command with the `ON CONFLICT (hash) DO NOTHING` clause. By using cryptography, we shifted the entire computational burden of deduplication away from our Node.js memory and onto the highly-optimized B-Tree indexes of the PostgreSQL C-engine. The execution time for deduplicating and inserting 1,000 articles dropped from 40+ seconds to roughly 3 seconds.
What I prioritized
Theoretical concepts applied to data pipelines:
- SHA-256 Hashing. Transforming variable-length URLs into fixed, deterministic cryptographic signatures.
- URL Normalization. Stripping volatile tracking parameters to find the true root identity of a data node.
- Pushing Logic to Metal. Leveraging PostgreSQL's ON CONFLICT clauses to avoid application-layer memory exhaustion.
- Batch Upserts. Executing massive bulk mutations in a single network round-trip.